 The A.I. Daily
Issue 2026-11-18 · Industry · 开源 · 研究 · 模型发布
Running 180B MoE inference in 32GB of RAM with Transformers
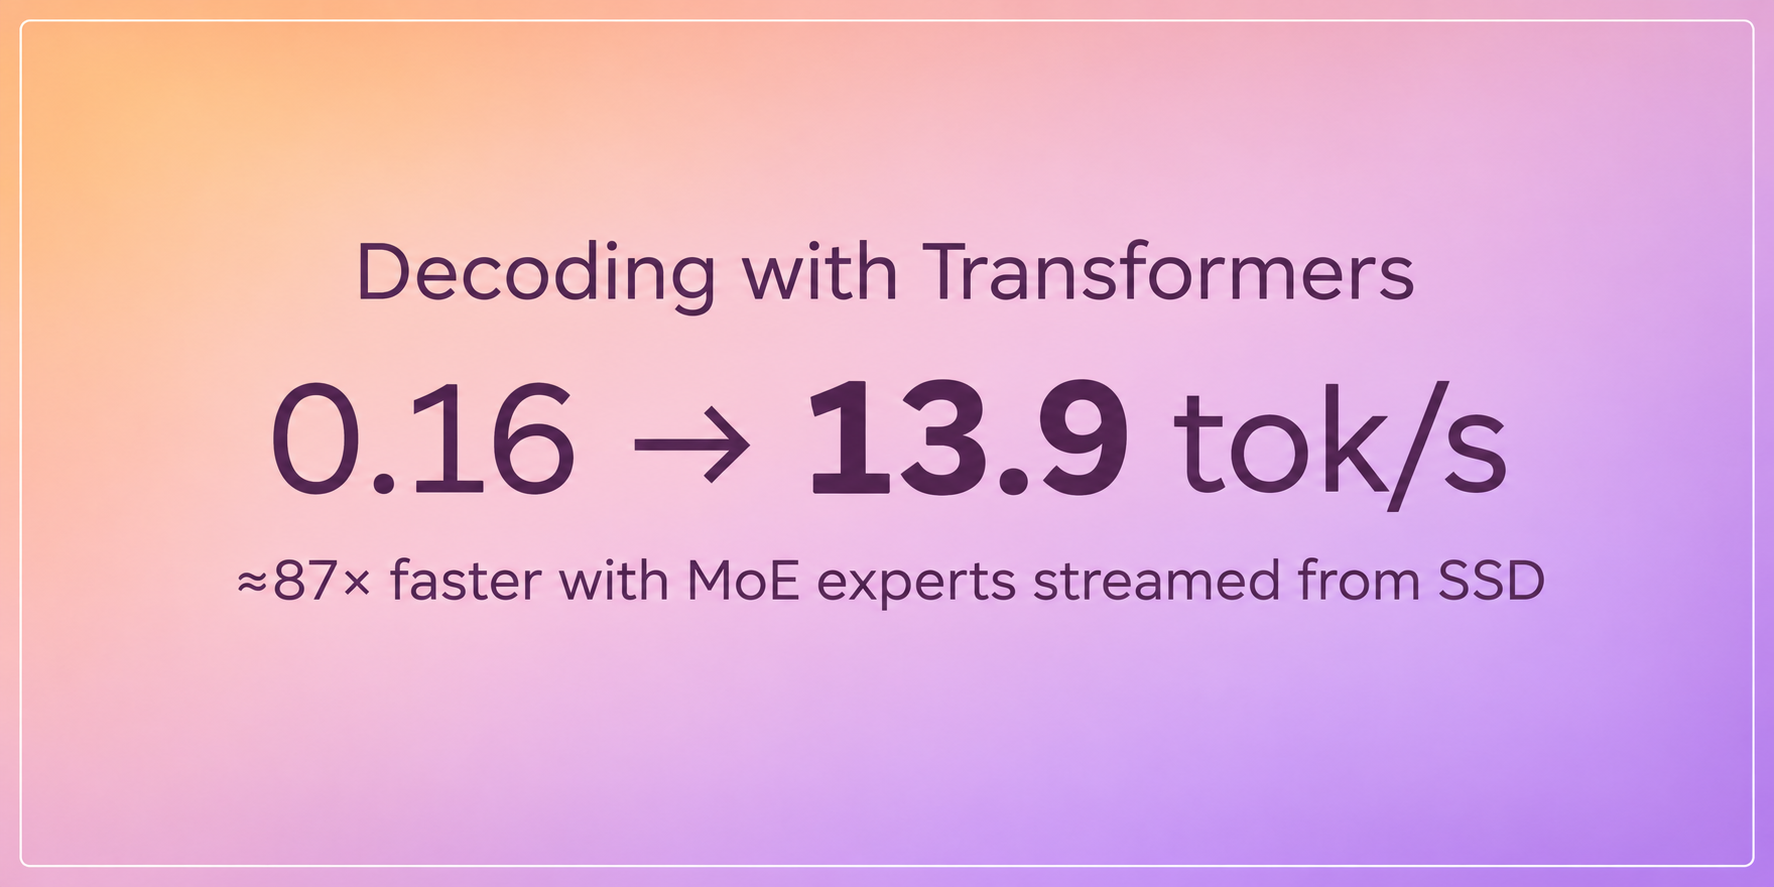
A Hugging Face blog post shows that streaming MoE experts from SSD lets a 180B-parameter model run in 32GB of RAM with Transformers, reaching token generation within 6% of Strata. Since experts make up over 90% of MoE weights, keeping only hot experts in VRAM enables large models on consumer hardware.
Read original ↗- Community tests full n-gram table for Qwen 3.8 Flash Next
- OpenMed 3.0 ships: Apache-2.0 clinical AI that runs fully local
- Community Tip: Use LoRA Instead of Downloading Full Abliterated Models
- llama.cpp Has Caught Up to a Vibe-Coded Engine, Benchmarks Show
- Open-source inside-llm visualizes LLM internals and quantization gaps