 The A.I. Daily
Issue 2026-11-14 · Industry · 模型发布 · 开源 · 芯片
GLM-5.3 Served via vLLM on Two DGX Stations at 607.8 tok/s
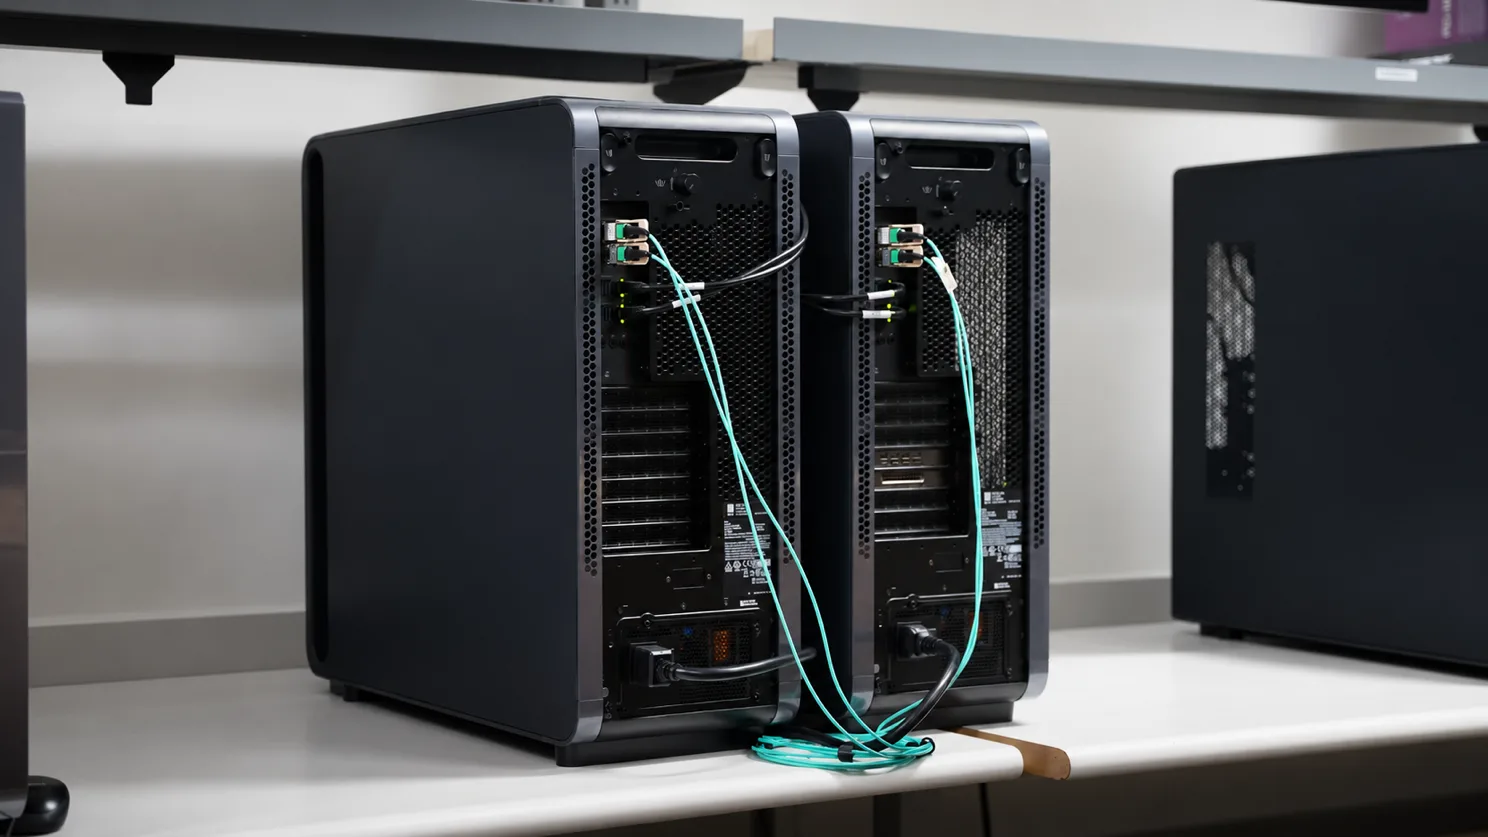
GLM-5.3 NVFP4 is a quantized 753B-parameter MoE model activating 40B parameters per token; its ~464GB of weights exceed the 252GB HBM3e on one GB300 GPU. Two NVIDIA DGX Stations linked over ConnectX-8 RDMA serve it via vLLM with tensor parallelism (TP=2) behind one OpenAI-compatible endpoint. On SPEED-Bench Coding, throughput peaked at 607.8 tok/s at concurrency 16, dropping to 385.0 tok/s at concurrency 32 with 453.5s mean latency.
Read original ↗- Open Models Debate: Weighing Safety Against Democratization
- User Shares 8x3090 AI Rig Build, Balancing Performance and Heating
- Cloudflare discloses cross-request KV cache leak in GLM-5.3
- NVIDIA showcases local AI hardware lineup at GTC Berlin
- Study Finds Speculative Reward Hacking Common in Coding Agents