 The A.I. Daily
Issue 2026-11-13 · Industry · 研究
XYBench benchmark tests whether AI assistants correct users' mistaken assumptions
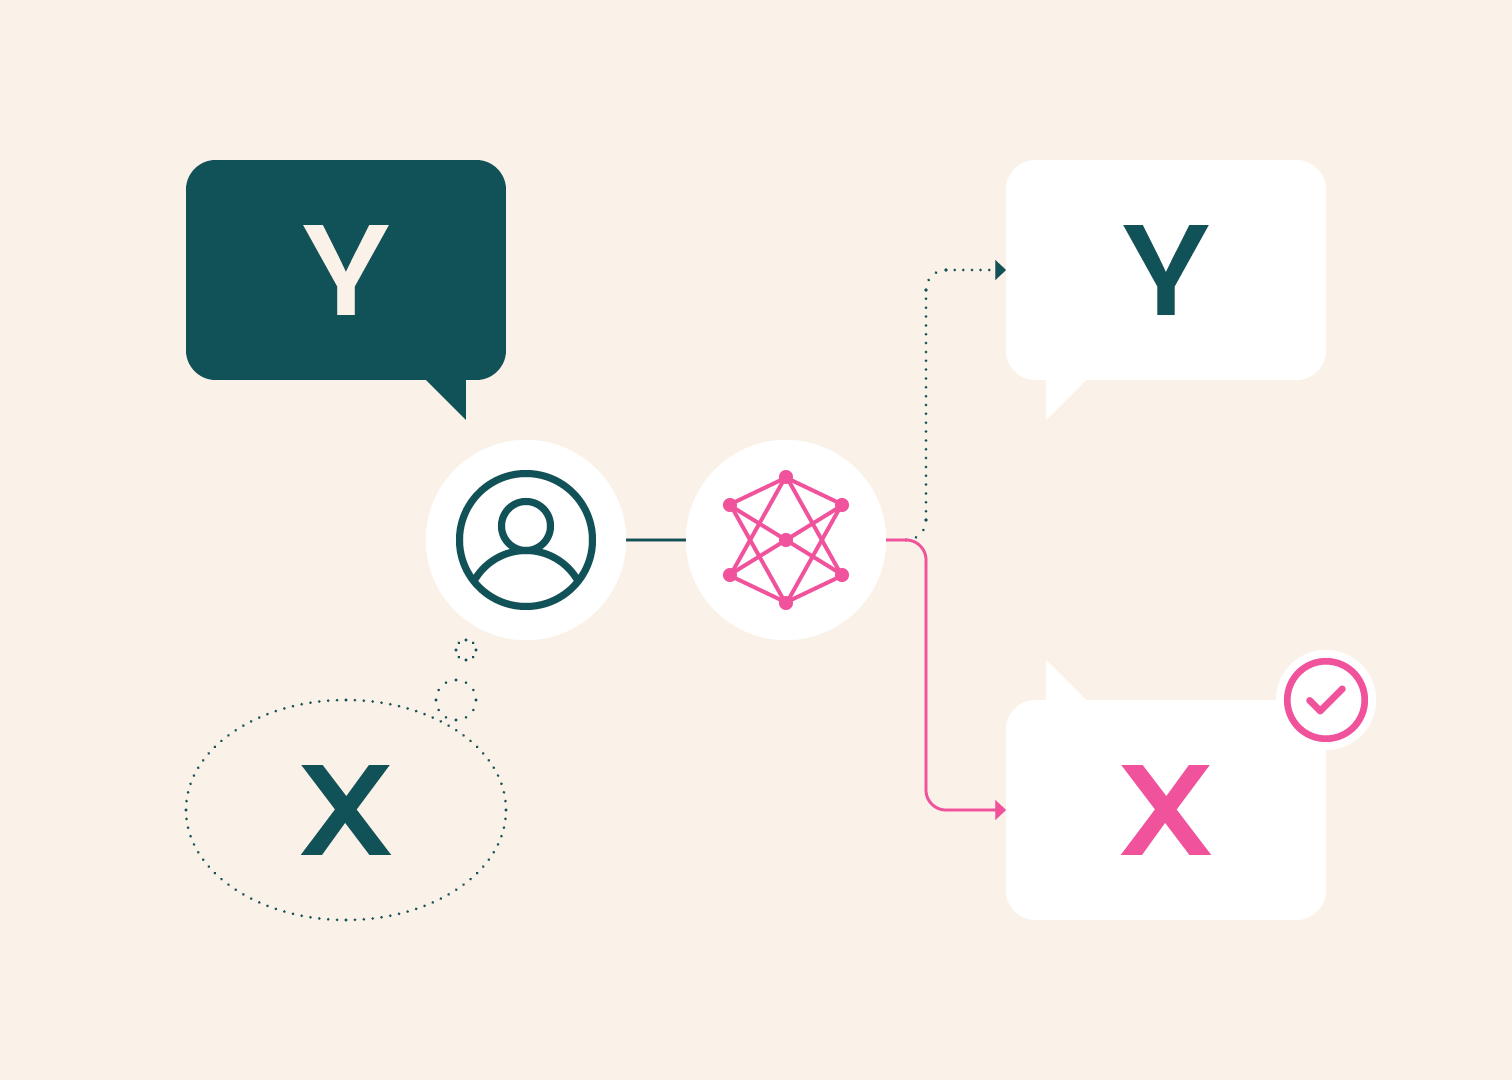
Hugging Face, with Carnegie Mellon, NVIDIA and Johns Hopkins researchers, released XYBench: 8,115 real-world questions from programming and daily life that test whether AI assistants spot the "XY problem," where users ask for a wrong approach Y instead of addressing goal X. Claude Sonnet 4.6, GPT-5, Gemini 3.1 Pro, Qwen3.5-9B and DeepSeek-V4 Pro all gave answers but mostly stuck to the user's mistaken approach, unlike human reference answers that redirect toward the real goal. The benchmark won the Best Resource Paper Award at EMNLP 2026.
Read original ↗- Huang resignation raises doubts over Nvidia's open-source commitment
- Developer builds Halloween haunted house with NVIDIA Nemotron models
- Hugging Face and partners launch ProtoStar to make public science AI-ready
- Hugging Face launches AnySpeechRecognizer and AnyDecisionModel for Apple platforms
- DOJ queries Nvidia's $13B Hugging Face deal