 The A.I. Daily
Issue 2026-10-14 · Industry · 研究 · 开源
Parsimony benchmark measures how much code AI models add
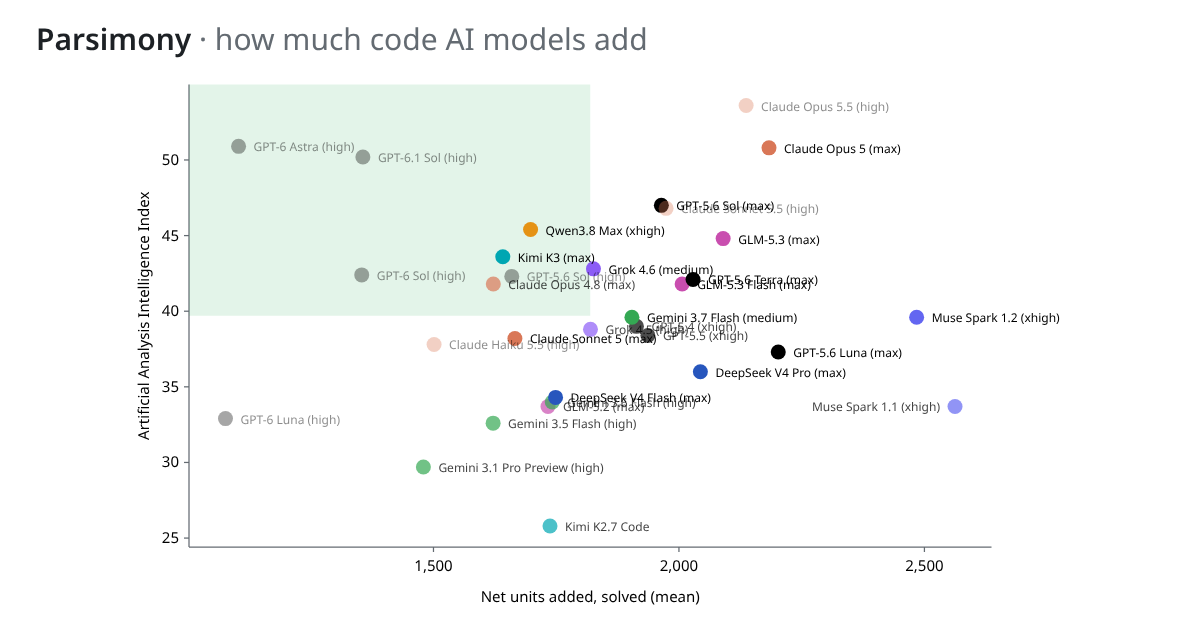
The open-source Parsimony benchmark measures net code units added by AI models, not just solve rate or token cost, to capture code bloat in long-term projects. It counts syntax elements in public patches from DeepSWE, SWE-bench Verified and Live, subtracting deletions; since GPT-6 and Claude 5.5 lack public patches, the author ran a few tasks himself, shown unranked.
Read original ↗