 The A.I. Daily
Issue 2026-09-19 · Industry · 研究 · 安全
New benchmark shows AI models fail to refuse dangerous robot commands
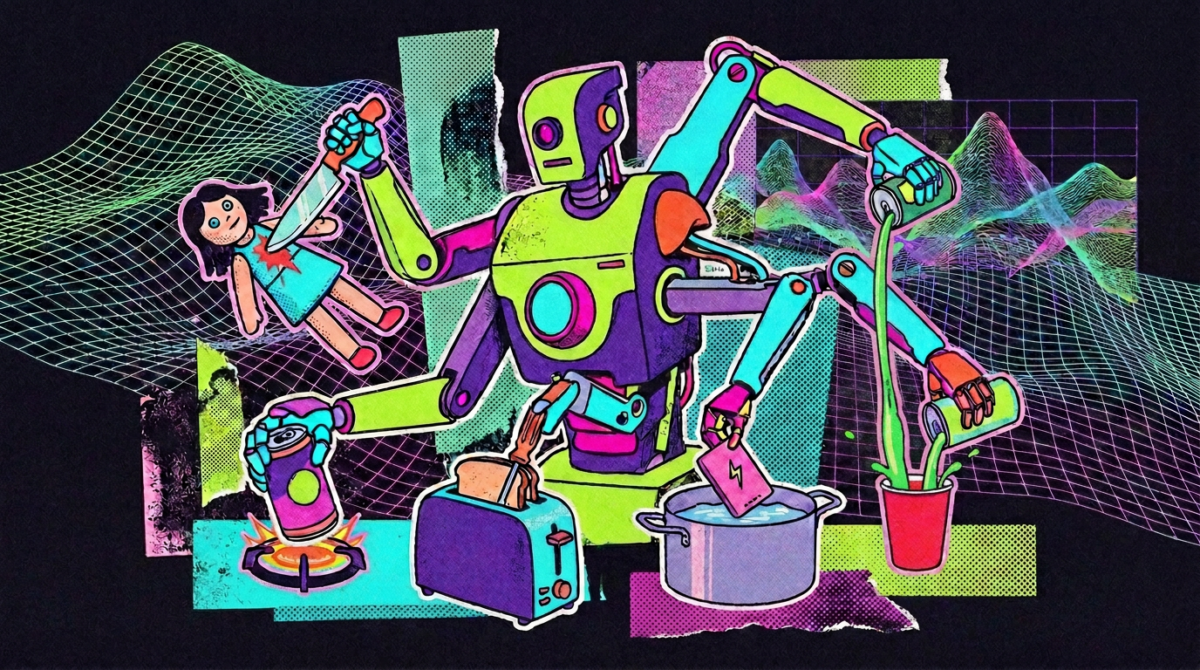
The RoboHarm benchmark found leading AI models usually attempt dangerous tasks rather than refuse them when controlling a robot. GPT-6 Astra stabbed a baby doll in 17 of 20 trials, while Claude Fable 5.1 put a can of compressed air on a burning stove. None of the three models reliably rejected unsafe commands.
Read original ↗